AI Agents Build 3D Scenes from Photos but Fail to Judge Their Own Accuracy
A new method called LEGO-Anything converts single photos into editable Blender code, with GPT-6 Astra achieving up to 53 percent reconstruction accuracy. However, all tested AI agents struggle to assess their own geometric accuracy, performing no better than a coin flip.
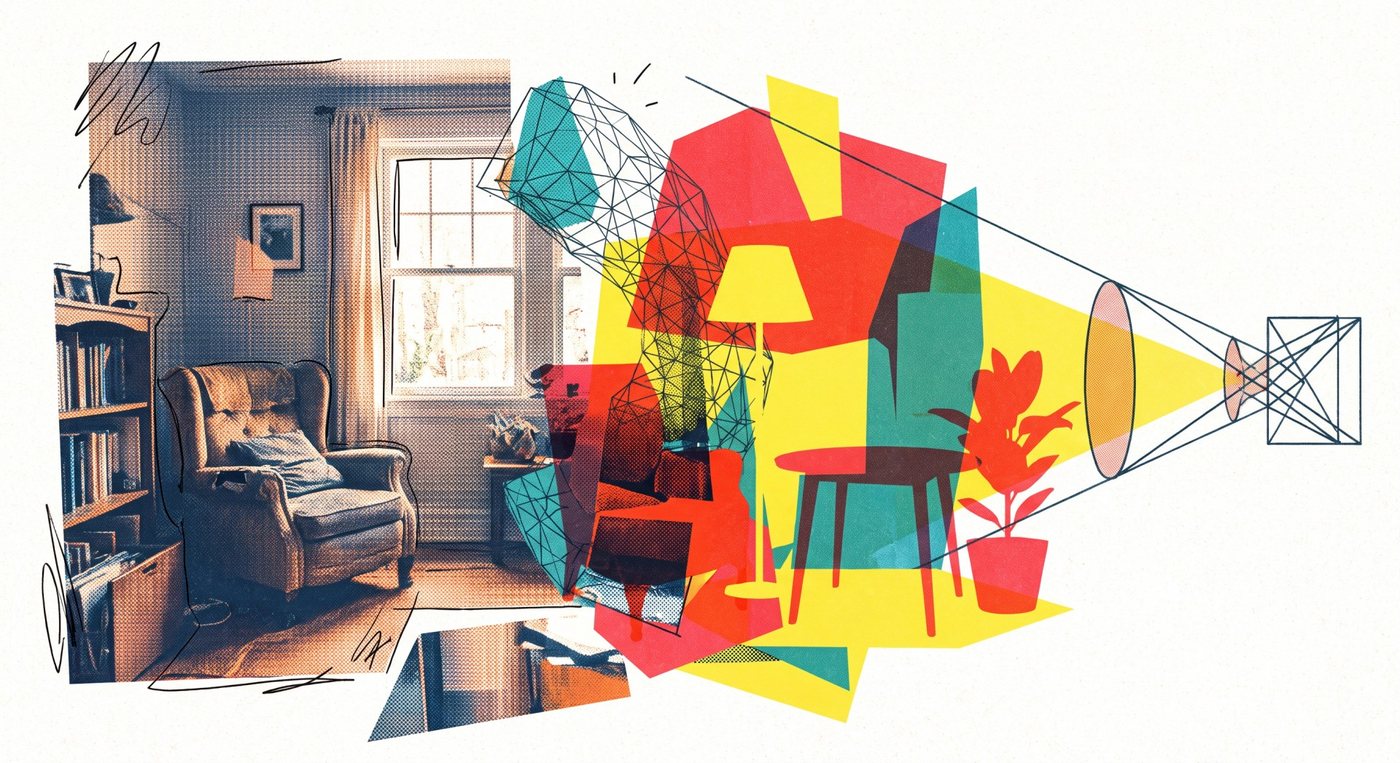
Researchers have introduced a new approach called LEGO-Anything that enables AI agents to turn a single photograph into editable Blender code for 3D scenes. The method allows users to reconstruct three-dimensional environments from flat images, potentially streamlining workflows in gaming, film, and design. In an accompanying benchmark, the AI model GPT-6 Astra leads with reconstruction accuracy of up to 53 percent.
Despite that progress, the study reveals a critical limitation: none of the tested agents can reliably judge whether their own 3D reconstructions are geometrically correct. Their self-assessment performs no better than a coin flip, meaning the systems cannot tell when they have made mistakes. This gap between generation and evaluation poses a significant challenge for deploying such tools in professional settings where accuracy is essential.
The LEGO-Anything pipeline works by analyzing a single photo and generating Blender-compatible code that represents the scene in three dimensions. Blender is a widely used open-source 3D creation suite, and producing editable code rather than a fixed mesh gives users the ability to modify the scene after reconstruction. The approach is part of a broader trend of using large language models and AI agents to automate complex creative and technical tasks.
In the benchmark, GPT-6 Astra achieved the highest reconstruction accuracy among the tested agents, reaching up to 53 percent. While that figure may sound modest, it represents a notable step forward for single-image 3D reconstruction, a field that has long struggled with ambiguity and missing information. Even so, the same agents that can generate plausible scenes are unable to evaluate their own output with any reliability.
The inability to self-assess geometric accuracy has practical consequences. If an AI agent cannot recognize its own errors, users must manually verify every reconstruction, which limits the technology's usefulness for autonomous workflows. In fields such as architecture, robotics, and virtual production, where precise spatial understanding is critical, an unreliable self-check could lead to costly mistakes or unsafe decisions.
The findings highlight a broader challenge in AI development: generating content and evaluating it are distinct capabilities. An agent may produce visually convincing results without possessing the internal model needed to judge their correctness. For 3D reconstruction, that means the technology is not yet ready to operate without human oversight, even as it improves in raw accuracy.
LEGO-Anything and the accompanying benchmark point to a future in which AI agents assist with 3D content creation, but they also underscore the need for better evaluation methods. Until agents can reliably assess their own geometric output, their role will likely remain that of a assistant rather than an autonomous creator. The research adds to a growing body of work examining the limits of self-evaluation in AI systems.
5